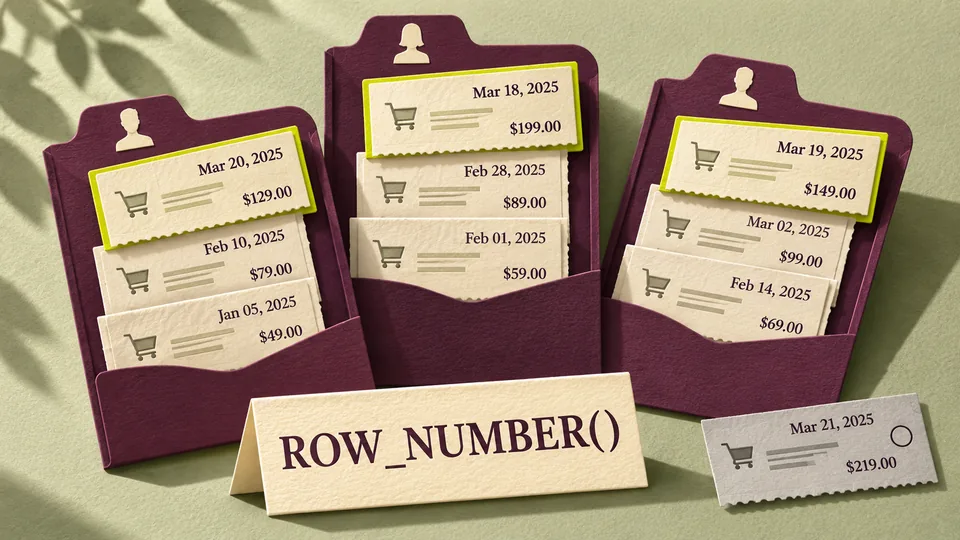
A reporting screen often needs one complete order per customer: the newest order that is currently paid. A maximum timestamp alone does not answer which row wins when two orders share that timestamp. This SQL ROW_NUMBER example makes that choice explicit and runs locally with Python and SQLite.
The business rule here is precise: filter to paid orders, sort each customer's candidates by order placement time descending, and break timestamp ties by the higher order ID. This is not a report of the latest payment settlement; the fixture has no payment timestamp. A customer with no paid order is absent from the result.
Prerequisites and the small fixture
Use Python 3.10 or newer with its sqlite3 module and SQLite 3.25.0 or newer. SQLite added window functions in release 3.25.0. There are no pip dependencies or database server credentials. Download and extract the complete runnable SQL example ZIP, then open a terminal inside sql-latest-paid.
Keep the two SQL files beside demo.py. Run python demo.py for the report and python -m unittest -v for the tests. Use python3 if that is your interpreter's command. To inspect your environment, run python -c "import sys, sqlite3; print(sys.version); print(sqlite3.sqlite_version)".
The schema below stores illustrative amounts as integer cents. All sample times are UTC in the same fixed-width YYYY-MM-DD HH:MM:SS format, without offsets or fractional seconds. SQLite supports text representations for date and time, but declaring TEXT does not validate a timestamp. Real input must be validated and normalized before this lexical ordering is appropriate.
1. Create schema.sql
CREATE TABLE orders (
    order_id INTEGER PRIMARY KEY,
    customer_id INTEGER NOT NULL,
    placed_at TEXT NOT NULL,
    status TEXT NOT NULL CHECK (status IN ('paid', 'pending', 'cancelled')),
    total_cents INTEGER NOT NULL CHECK (total_cents >= 0)
);
The sample uses only the statuses listed in the constraint. It intentionally has no customer master table: customer 3 appears in orders but has no paid order. If a dashboard must also show customers who have never ordered, that is a separate requirement requiring a customer source.
2. Save the ranking query as latest_paid.sql
WITH ranked_paid AS (
    SELECT order_id, customer_id, placed_at, total_cents,
           ROW_NUMBER() OVER (
               PARTITION BY customer_id
               ORDER BY placed_at DESC, order_id DESC
           ) AS rn
    FROM orders
    WHERE status = 'paid'
)
SELECT customer_id, order_id, placed_at, total_cents
FROM ranked_paid
WHERE rn = 1
ORDER BY customer_id;
In SQLite's window-function documentation, ROW_NUMBER assigns consecutive positions within a partition using its ordering. Here customer_id defines each partition, and the two sort keys give every eligible order an unambiguous position. The outer query keeps position one. Its final ORDER BY controls the report's presentation separately from the ranking order.
The paid predicate belongs inside the common table expression because eligibility comes before selection. With this fixture, ranking every order first would put pending order 104 ahead of customer 1's paid orders. Filtering that winner afterward would remove customer 1 rather than return paid order 103.
3. Add demo.py and run it
"""Run a fictional SQL fixture in memory; no files or server are modified."""
from pathlib import Path
import sqlite3

ROOT = Path(__file__).resolve().parent
SAMPLE = [
    (101, 1, '2026-11-01 09:00:00', 'paid', 1200),
    (102, 1, '2026-11-02 10:00:00', 'paid', 2500),
    (103, 1, '2026-11-02 10:00:00', 'paid', 2700),
    (104, 1, '2026-11-03 12:00:00', 'pending', 9000),
    (201, 2, '2026-11-01 08:00:00', 'paid', 800),
    (202, 2, '2026-11-04 14:00:00', 'cancelled', 5000),
    (301, 3, '2026-11-04 16:00:00', 'pending', 700),
]


def connect(rows=()):
    if sqlite3.sqlite_version_info < (3, 25, 0):
        raise RuntimeError('This example requires SQLite 3.25.0 or newer.')
    db = sqlite3.connect(':memory:')
    try:
        db.executescript((ROOT / 'schema.sql').read_text(encoding='utf-8'))
        db.executemany('INSERT INTO orders VALUES (?, ?, ?, ?, ?)', rows)
    except Exception:
        db.close()
        raise
    return db


def latest_paid(db):
    sql = (ROOT / 'latest_paid.sql').read_text(encoding='utf-8')
    return db.execute(sql).fetchall()


def main():
    db = connect(SAMPLE)
    try:
        print('customer_id | order_id | placed_at | total_cents')
        for row in latest_paid(db):
            print(' | '.join(map(str, row)))
    finally:
        db.close()


if __name__ == '__main__':
    main()
The runner opens a fresh in-memory database and closes it explicitly. The Python sqlite3 reference documents this connection mode and parameter placeholders. The fixture uses placeholders for row values; the SQL files are trusted project source, not uploaded SQL. No production database or existing local database file is accessed.
Expected output
customer_id | order_id | placed_at | total_cents
1 | 103 | 2026-11-02 10:00:00 | 2700
2 | 201 | 2026-11-01 08:00:00 | 800
Orders 102 and 103 have the same placement time, so 103 wins for customer 1. Pending order 104 is newer but is not eligible. Customer 2 retains paid order 201 despite a newer cancelled order. Customer 3 has only a pending order, so no row is returned for that customer. The amount comes from the selected order, not from whichever order has the highest amount.
Why not GROUP BY with MAX?
A grouped MAX(placed_at) produces a timestamp per customer. Selecting extra nonaggregated columns beside it is a trap: SQLite's bare-column rules include special behavior for a single MIN or MAX, but ties still leave the chosen row ambiguous. Joining the maximum timestamp back to orders can also return both tied rows. This lesson requires one row, so the explicit secondary order matters.
The higher-ID tie-break is a policy for this example. An ID is not proof of later payment, and a larger ID must not override a later placement timestamp. If the product needs every jointly newest order, change the requirement and query together rather than quietly removing the tie-break.
Tests and useful failure cases
On 5 November 2026, this fixture ran on Windows with Python 3.12.14 and SQLite 3.53.1. All twelve unittest cases passed. They cover exact sample output, timestamp ties, later time versus higher ID, reversed insertion order, newer unpaid orders, no paid orders, an empty table, independent customers and output sorting, the winning row's amount, unchanged table contents, duplicate IDs and invalid statuses. The extracted ZIP was independently run with the same checks and its demo matched expected-output.txt.
- Old SQLite: the runner raises a version requirement before creating the fixture. Check the library linked to your interpreter, not just a separately installed sqlite command.
- Missing source files: a FileNotFoundError means the SQL files were separated from demo.py or the package was incompletely extracted.
- Rejected input: duplicate order IDs and unknown statuses raise sqlite3.IntegrityError. Those are expected error tests, not failures to rank rows.
- Mixed dates or time zones: the schema does not normalize or reject them. Do not assume arbitrary date strings sort chronologically; add input validation before using this pattern with real data.
The ZIP includes test_demo.py, README.md and expected-output.txt alongside the three files printed above. This is an SQLite-tested correctness lesson, without a cross-database compatibility or performance claim. For production workloads, review the execution plan and indexes against real distributions. For a separate relationship-matching exercise, see our runnable SQL INNER and LEFT JOIN example.
Comments (0)
Join the discussion